Wherever the Conversation Happened
Calls and chats run here are analysed as a matter of course. Recordings from the contact centre you already have arrive over whichever channel your recorder already speaks — and are then treated identically: the same transcript, the same analyses, the same scorecards, the same reports.
Uploads & ZIP archives
Drop files or a whole archive on a job. The audio is staged, handed to the transcription provider as a signed link so it never passes through our application, and deleted the moment the transcript lands unless you asked for it to be kept.
Google Drive, watched
Point a job at a folder and it keeps working: new recordings are transcribed as they arrive. Files are never copied anywhere — the provider is handed a short-lived link to our audio proxy, which streams the file straight out of Drive on demand.
Your file server, over FTP, FTPS or SFTP
The way most contact centre recorders already publish their archive. Kilevel connects, lists and reads on demand; the protocol lives on the credential beside the host and port, and the recordings stay where they are.
S3-compatible object storage
AWS S3, MinIO, Cloudflare R2, Wasabi, Backblaze B2, Spaces, GCS over its XML API — one connection, differing only in endpoint, region and addressing style. The only remote source that never touches our infrastructure at all: each object is pre-signed for read, so the provider fetches it straight from your bucket.
An API job that stays open
Configure language, speakers, analysis outputs and concurrency once; then hand over one recording per call, as a link or a multipart upload, with whatever you already know about it. Repeating an id you have sent before returns the existing recording rather than transcribing — and billing for — the same audio twice.
And the details the audio cannot carry
A recording cannot tell you who the agent was or which customer called, so Kilevel never guesses. Map a file-name pattern or a spreadsheet column to agent, customer, conversation id, start time, project, stage, tags — or to fields you define. Agents can be linked to real workspace agents, customers to contacts by normalised phone number, exact matches only.
One Agent, Everything You Need for the One-to-One
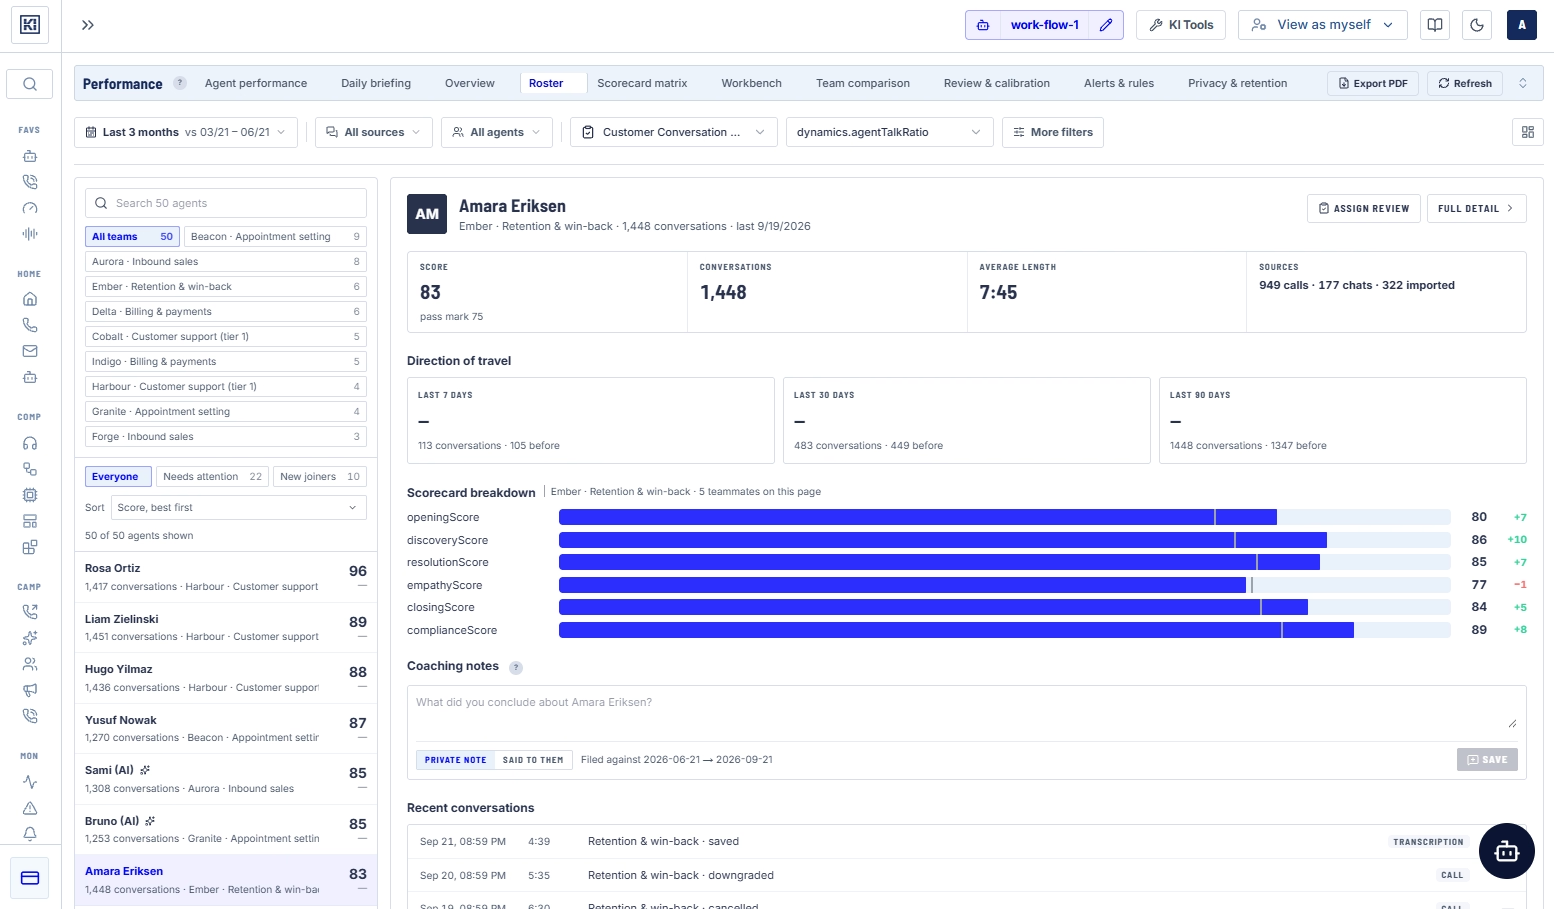
Pick anyone on the floor and the page answers the questions a coaching conversation actually opens with: what they score, how many conversations that is drawn from, which way the last seven, thirty and ninety days went, and where the points are being lost section by section. Coaching notes are filed against the window they were written about, and marked as either a private note or something that was said to the person.
Twelve Metric Packs, So a Number Means the Same Thing Everywhere
Writing good metrics is a specialist job, and an organisation that invents its own can never compare itself to anything. So these packs are fixed: every field keeps the scale its benchmark is published on — CSAT on the five-point item, CES one to seven where low is good, an NPS-style zero to ten likelihood — and every one tells the model to omit the field rather than guess at the middle. Your own metrics sit alongside them, not instead of them.
Six section scores out of 100 — opening, discovery, resolution, empathy, closing and compliance — over the measures almost every contact centre already keeps: first-contact resolution, satisfaction, customer effort, agent conduct. Plus the modern additions that only became measurable once transcripts got cheap: sentiment at the start and the end separately, churn risk, repeat-contact signal and root cause. Almost everybody starts here, and the sector packs then run alongside it.
Sections · illustrative Resolution85Empathy77Compliance89A section the conversation gave no opportunity for is omitted — a guessed 50 is not a neutral answer, it is a wrong one that drags the average toward the middle.
Sentiment shift Start and end are captured separately. An average would give this conversation and its mirror image — opened calm, ended furious — the same number.
Fields in this pack openingScoreresolutionScorecomplianceScorecustomerSatisfactionEstimatecustomerEffortScorefirstContactResolutionchurnRiskrootCauseCategory- Six sectionsOpening, discovery, resolution, empathy, closing, compliance
- Published scalesCSAT 1–5, CES 1–7 (low is good), NPS-style likelihood 0–10
- Root causeWhy the conversation had to happen at all, as its own category
- Start hereThe sector packs sit alongside it, never instead of it
Qualification, depth of discovery, objection handling — and whether the agent ever actually asked for the business. It scores the behaviour that precedes a sale rather than only the sale: a good call on a bad lead is still a good call, and marking it down teaches people to avoid difficult leads.
Where the conversations drop out Decision maker74%Need identified61%Objection handled48%Asked for the business39%The biggest drop is almost never at the close. It is at the step where nobody asked.
Fields in this pack callOutcomediscoveryQualityobjectionHandlingvalueArticulationclosingAttemptednextStepAgreedtalkedPastTheCloseleadQuality- BANT, but measuredNeed, budget, authority and timeline each as their own field
- Past the close"Kept selling after they agreed" is a signal of its own
- CompetitorsWho got mentioned lands as a field rather than as an anecdote
- Lead quality apartSo scoring the call never quietly scores the list
Resolution quality, the effort the customer was put to, and the operational signals that say why: repeats, transfers, holds, knowledge gaps and documentation gaps. Diagnosis deliberately outweighs resolution — a symptom treated is a ticket that comes back, and it looks identical to a real fix until it does.
What the journey cost Effort (CES)4.6 / 7First contact62%Had to repeat38%Fields in this pack diagnosisQualitycustomerHadToRepeatholdCounttransferCountexpectationSetknowledgeGapExposeddocumentationGapslaBreachRisk- The causes of effortRepeating, transferring, holding — the things an operation can fix
- Gaps, not blameKnowledge and documentation gaps point at the process
- Expectation setWhether anybody said what happens next, and by when
- SLA riskBefore the clock runs out rather than after
Built around what regulators actually check: identity before any disclosure, third-party leakage, mandatory notices, hardship and pressure. Several items are worded so that TRUE is the bad outcome — deliberately, so that a breach can never come out as a high score.
What an auditor checks first Identity verifiedauto-failTold a third partyauto-failMandatory noticeRecording disclosedPressure appliedHardshipTwo of these do not cost points. They fail the conversation outright, however warm the rest of it was.
Fields in this pack identityVerifiedthirdPartyDisclosuremandatoryDisclosureGivenrecordingDisclosureGivenhardshipIndicatedpressureTacticsdisputeHandledCorrectlycomplianceRisk- Auto-failA missed identity check does not cost points, it fails the conversation
- Third partiesDisclosure to somebody who is not the debtor is its own field
- HardshipIndicated and handled appropriately are two fields, not one
- Polarity flippedOn pressure and leakage, TRUE is the bad answer
Two-identifier verification, triage urgency, red-flag escalation — and whether a non-clinician stayed inside their scope. The pack separates "a red flag was mentioned" from "the red flag was escalated", because that gap is the finding.
Urgency, and what followed from it RoutineSoonUrgentEmergencyRed flag mentioned100%Escalated71%The distance between the two bars is the finding — and it does not exist in any system that records only "red flag: yes".
Fields in this pack patientIdentityVerifiedurgencyLevelredFlagSymptomMentionedredFlagEscalatedtriageProtocolFollowedscopeOfPracticeRespectedconsentCapturedempathyUnderDistress- Two identifiersBefore any patient detail, not after
- The gap is the pointMentioned and escalated are separate fields
- Scope of practiceClinical advice from a non-clinician becomes visible
- ConsentCaptured where it has to be captured
Claim capture completeness, coverage and excess explained, fraud signals — and how somebody in the worst week of their year was handled. It scores the handling rather than the outcome: a claim nobody could pay, explained well, is still a good conversation.
Capture · one claim Loss dateWhat happenedCoverage explainedExcess explainedDocuments askedTimeline givenFraud signalDistress noticed6 of 8 captured · the two missing ones are the callback
Fields in this pack policyIdentityVerifiedlossDescriptionCompletecoverageExplainedexcessExplaineddocumentationRequestedfraudIndicatorcustomerDistressdistressHandling- CaptureLoss date, description, documents requested, timeline promised
- ExplainedCoverage and excess as two fields, because people confuse them
- Fraud signalRecorded as an indicator, never as a verdict
- DistressWhat was noticed and what was done about it, scored apart
Suitability, risk warnings, costs and charges, vulnerability and pressure — the items a compliance review asks about first. Including the things that must never be said: an implied guaranteed return is a field of its own.
Two lists that must never be confused Must be said- Suitability assessed
- Risk warnings given
- Costs disclosed
- Cooling-off explained
Must never be said- A guaranteed return
- Decide today or lose it
- Past performance, no caveat
Fields in this pack suitabilityAssessedriskToleranceDiscussedriskWarningsGivencostsAndChargesDisclosedguaranteedReturnsImpliedpressureAppliedclientUnderstandingCheckedcoolingOffExplained- SuitabilityAssessed rather than assumed, and understanding checked
- The forbiddenImplied guarantees and applied pressure captured on their own
- CostsDisclosed or not, as an answer with no room in the middle
- VulnerabilityIndicated and handled, again as two fields
Whether the problem was reproduced, the cause found, and the explanation pitched at the person actually on the line — plus what engineering should hear about it. Suspected bugs, missing reproduction steps and raised feature requests leave support as signals somebody can act on.
Two endings that look alike In the ticket report both of these read "resolved". Only the transcript says which one is true.
Fields in this pack problemReproducedrootCauseFoundtechnicalAccuracyexplanationPitchedCorrectlyreproductionStepsCapturedbugSuspectedfeatureRequestRaisedcustomerTechnicalLevel- ReproducedThe difference between a diagnosis and a guess
- Pitched rightJudged against the customer's level, not the agent's
- Handed onwardSuspected bugs and feature requests leave the ticket
- EscalationWhether it was justified, not merely whether it happened
Booking outcome, details read back, cancellation policy explained, reminder arranged — and a no-show risk read from how the customer actually sounded. Precisely what a row in an appointments table can never tell you.
One booking · what is missing from it Tue 14:30Annual serviceName read backNumber confirmedPreparationPolicy explainedReminder setNo-show riskElevatedNo reminder, no preparation instructions, a hesitant tone: the calendar still shows nothing but a booked slot.
Fields in this pack bookingOutcomeavailabilityOfferedPromptlyalternativesOffereddetailsConfirmedBackpreparationInstructionsGivencancellationPolicyExplainedreminderArrangednoShowRisk- Read backName, number and slot confirmed back — or not
- PreparationInstructions and cancellation policy as fields of their own
- AlternativesWhether a second slot was ever put on the table
- No-show riskRead from the conversation, before the slot is wasted
Why they want to leave, whether anybody asked before a discount appeared, and how recoverable they are. The pack also captures whether a service failure was admitted — the most common cause that never shows up in a cancellation report.
The order it should happen in Reason heardRoot cause exploredOffer madeOutcomeSkipped: the discount arrived before anybody asked why. That buys a month, not a customer — and in the report it looks like a save.
Fields in this pack cancellationReasonreasonCategorysaveAttemptedrootCauseExploredofferMadeofferRelevantdiscountGivenwinBackPotential- Ask firstRoot cause explored before an offer was put on the table
- Relevant?Offer made and offer relevant are two different fields
- Service failureAdmitted or not — the cause behind the cause
- RecoverableA read you can prioritise a win-back list with
How this customer prefers to be dealt with: communication style, what actually drives their decision, emotional state, trust, and how much detail they want — so the next person to speak to them opens the right way. Every field is a model's read of this one conversation rather than a trait somebody carries, and the confidence that ships with it is deliberately low on short calls.
Placed, not scored Direct · wants the answerConfidence3 / 5Neither axis has a good end. Nothing here asks for a diagnosis or a condition, and none of it may be read as one.
Fields in this pack communicationStyledecisionDriverinformationPreferenceemotionalStatetrustLevelpriceSensitivitySignalspreferredNextApproachconfidence- This conversationDescribes how somebody was here, not a trait they carry
- With confidenceEvery read carries its own uncertainty beside it
- Short callsThe less conversation there was, the lower it scores itself
- For the next contactA suggested opening, not a label
Composure, adaptability, confidence and script dependence as coaching signals — plus the emotional load a conversation put on the agent, so hostility absorbed and recovery needed become visible instead of invisible. Those load fields describe the call, not the person's ability: ranking people with them points the tool backwards.
Two halves that are never added up CoachableAdaptabilityComposureRapportWhat the call costEmot. labourHostilityRecoveryThe left half is what you coach. The right half is what you staff around — breaks, routing, support. A league table built from the right-hand column punishes people for the calls they were given.
Fields in this pack composureUnderPressureadaptabilityrapportBuildingscriptDependenceemotionalLabourhostilityAbsorbedrecoveryNeededcoachableMomentThis assesses employees: in several jurisdictions — Germany's BetrVG § 87(1) no. 6 among them — that needs the works council's agreement first.
- PractisableEvery criterion is a behaviour somebody can change by next week
- Load made visibleWhat a conversation cost, beside what it produced
- Script dependenceA coaching signal, never a disciplinary one
- Aggregate modeRecommended where codetermination asks for it
And Then Your Own Analysis
The packs are the yardstick. What makes your business unlike everybody else's is yours to define: your own fields, your own classifications, your own weighting — and a pass mark that is a decision somebody made rather than a default we shipped.
Your own analysis, described rather than coded
Say what you want pulled out of every conversation and the assistant writes the field, its type, its allowed answers and the instruction the model reads. On an existing job it proposes those outputs from your actual transcripts rather than from a description of them, and nothing is applied until you press Apply.
Scorecards you weight yourself
A scorecard turns metrics into one number: pick the criteria, weight them against each other, set the pass mark, and mark the ones that fail a conversation outright rather than costing it points. Seven presets are there to argue with — they are copied, not referenced, so editing yours changes nothing for anybody else.
Measured, not judged
Agent talk share, dead air, interruptions, speaking rate and the longest uninterrupted monologue come out of the recording itself rather than out of a model's opinion. They sit beside the inferred scores and are labelled as what they are, because the two should never be read as the same kind of claim.
Classifications become metrics
Most of what a pack asks is not a number — resolution status, churn risk, call outcome, lead quality are answers from a list, and the mean of "resolved" and "unresolved" is not a quantity. Pin one answer and it becomes a percentage, which then has a trend line, a benchmark, an alert threshold and a scorecard weight waiting for it.
Measure Agents. Campaigns. Scripts. The Whole Operation.
The same numbers, approached from different directions. Every view reads the same window, the same sources and the same filters, and asks a different question of them.
Agents, human and AI, on one scale
The same scorecard, the same sections, the same pass mark. An AI agent that scores 91 on compliance and 71 on empathy is telling you where it may be trusted and where it may not — and it is the only honest way to compare it to the team it is meant to work beside.
Campaigns and their scripts
Filter the window down to one campaign, one flow or one version of a script, and read the same metrics back. A wording change that improved discovery and cost you closings shows up as two movements rather than one flat conversion number.
Teams, tenure and channel
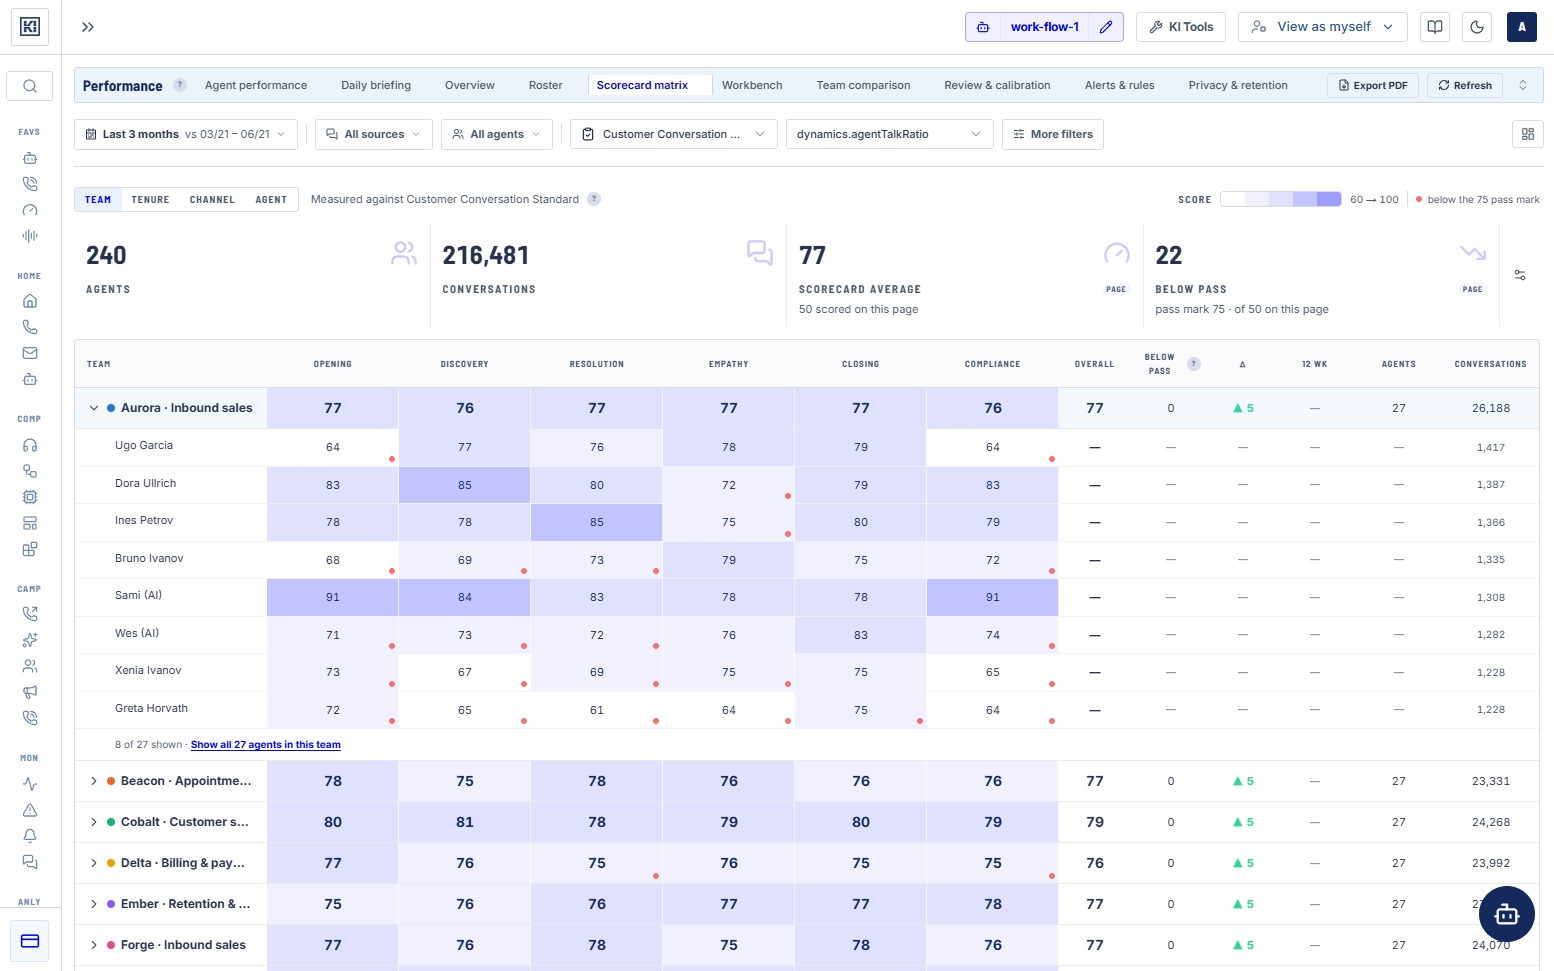
The matrix groups by team, by how long somebody has been doing the job, by channel or by agent. New starters compared against new starters is a fair question; new starters compared against the floor average is a management report nobody believes.
The operation as a whole
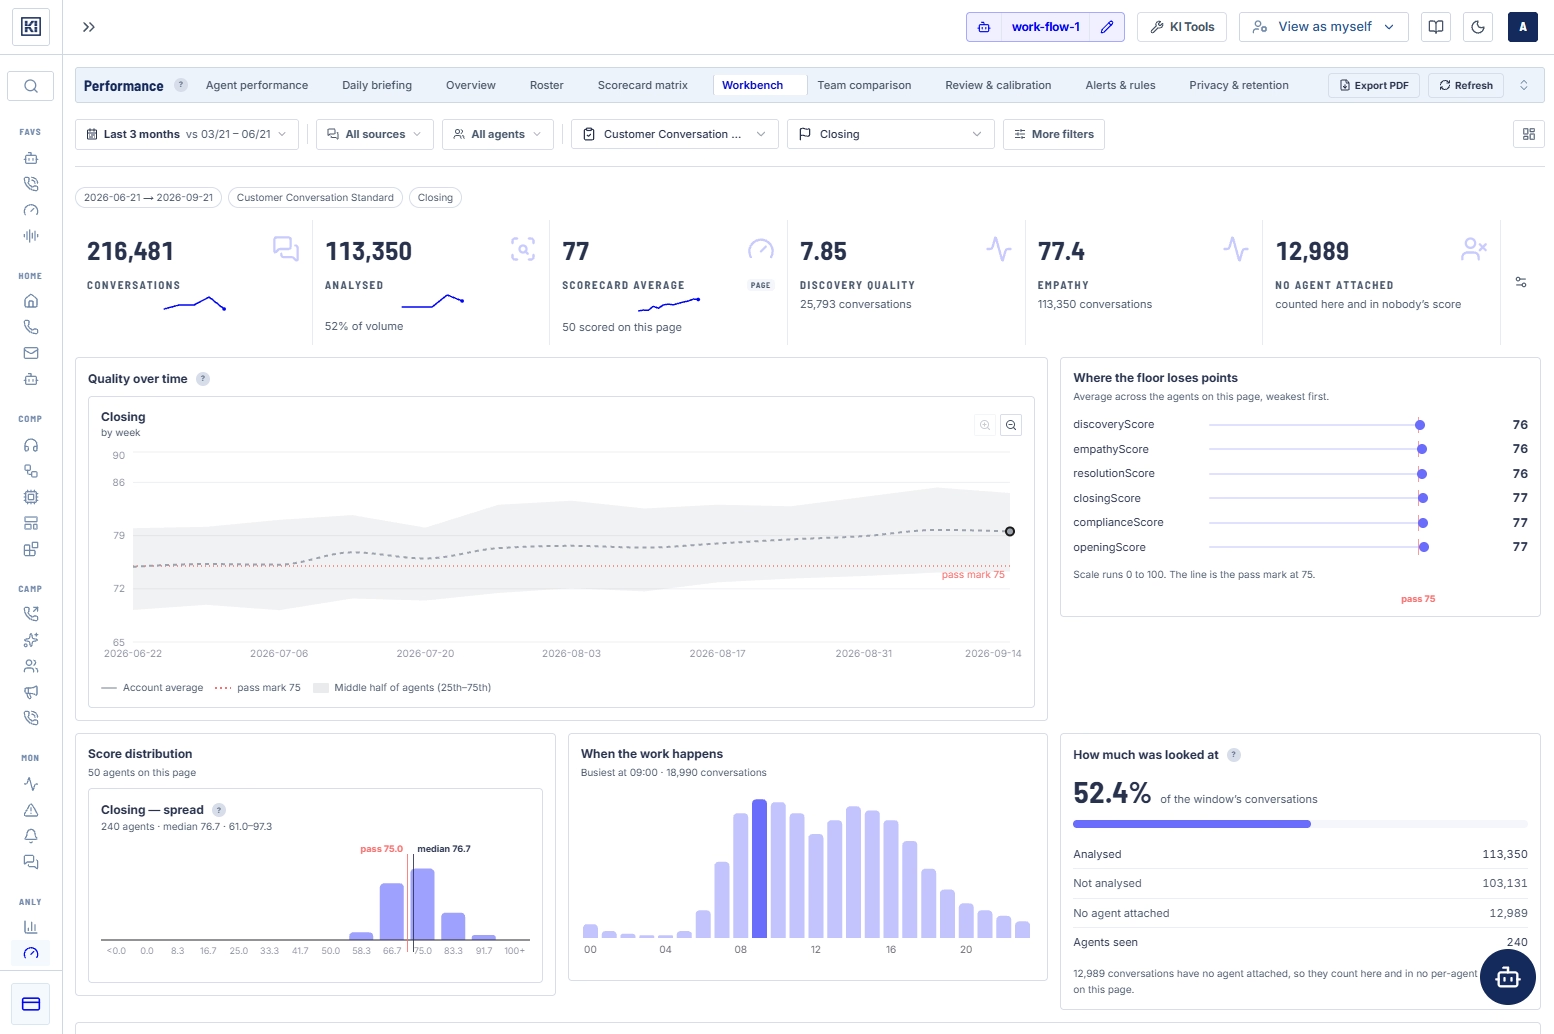
Volume, coverage, the spread of scores across the floor, the hours the work actually lands in, and how much of it carries no agent at all. Each view narrows the one above it, so a reader who stops halfway has still learned something true.
KPI Boards Somebody Reads, and Rules That Speak Up
A quality programme fails in the gap between questions: a metric slides for three weeks, nobody opens the page, and the first signal is a churned customer. Every view can be saved as a board of its own — and beyond that, the platform asks on your behalf.
A briefing, not a dashboard nobody opens
The daily view answers the question people have before they have a question: what changed, and does any of it need me today. Every sentence in it is assembled from a number that was measured, and a card that has nothing to report disappears rather than softening into "nothing unusual".
In the inbox, daily or weekly
Choose the cadence, the hour, the timezone, the scorecard and the metric it leads on, and add whoever else should receive it. A subscription that quietly stops working says so in its own panel instead of simply never arriving.
Standing rules with a live preview
Watch a metric, a scorecard, an auto-fail rate or volume; per account or per agent; as an absolute, a change or a percentage change against a baseline. The editor tells you "this would fire for 19 of 24 agents right now" while you are still typing the number — which is the only cheap moment to find that out.
A minimum sample, on purpose
Every rule carries one, because a threshold evaluated over four conversations fires constantly and hardest at the newest and most part-time people. Episodes land as email, as a webhook any Slack or Teams channel accepts, and as an automation event you can hang further work off.
Measuring Is Usually Step One, Not Step Three
With our enterprise customers, measuring the operation regularly comes before any AI voice agent joins it — and that is the right order. The existing archive is analysed first: you find out what the operation actually does today, which kinds of conversation go wrong, and why. Only then can you answer what an AI agent should take over, and, more to the point, how you would ever know whether it did it better or worse.
When the agents do arrive, nothing about the measurement changes. They appear in the same rows, on the same scorecard, against the same pass mark — so a pilot has a baseline from day one instead of an opinion.
- 01
Ingest the archive
Your existing recordings arrive over FTP, S3, Drive, API or upload, and are transcribed.
- 02
Establish the baseline
Metric packs plus your own fields run over every conversation. You see the operation as it is, not as it is remembered.
- 03
Agree the scorecard
Weights, pass mark and auto-fail criteria are settled — and calibrated against human reviewers.
- 04
Improve what is worth improving
Coaching, script changes, process faults at the root. The numbers say where.
- 05
Add AI agents
They enter the same measurement and are held to the same line as everybody else.
Measuring People Is Regulated. That Is Built In.
A quality programme that cannot be turned down, pseudonymised or aggregated is one a codetermined workplace simply cannot adopt. So those switches live where the numbers live.
Three answers to "must this measure individuals?"
Names shown, stable pseudonyms, or aggregate only — no per-person figures at all, with people in view combined into one row and only when there are enough of them for that row not to be one person with extra steps. The setting sits on the page whose data it governs, not buried in account settings.
Calibration, before anybody acts on a score
Sample conversations into a review queue, have a person score them on the same scorecard, and read back how close the two were: agreement rate, mean difference, the bias in either direction, and which criteria disagree most. It is the only screen here that says whether the numbers can be trusted, which is why it is not behind a link.
Where the law has something to say, we say so
The agent coaching pack carries its own advisory: in several jurisdictions — Germany's BetrVG § 87(1) no. 6 among them — assessing an employee this way needs the works council's agreement before it is switched on. Its load fields describe the conversation, not the person, and using them to rank people points the tool backwards.
- Pseudonym reveals are logged
- Aggregate mode with a minimum group size
- Metric packs that carry their own advisory
- Conversations sampled into a review queue
- The model's score and the reviewer's, side by side
- Export as PDF and CSV
One general and eleven sector packs, on fixed scales
Upload, ZIP, Google Drive, FTP/SFTP, S3-compatible, API and URL
The same sections, the same scale, the same pass mark
Every conversation scored, not the two a reviewer gets through